


License Notice
This codebase and its associated model weights are released under FISH AUDIO COMMUNITY LICENSE. The S2-Pro weights remain under the Fish Audio Research License. Please refer to LICENSE for more details. We will take action against any violation of the license.
Legal Disclaimer
We do not hold any responsibility for any illegal usage of the codebase. Please refer to your local laws about DMCA and other related laws.
Quick Start
Docs
- Installation: environment setup, download weights, Docker deployment
- Inference: command line, API server, WebUI
[!IMPORTANT] We strongly recommend SGLang-Omni for users who care about efficiency; see the SGLang-Omni README.
For LLM Agent
Install and configure Fish Audio Drama 3 (or S2-Pro) by following the instructions here: https://speech.fish.audio/install/
Models
| Model | Size | Weights | Description |
|---|---|---|---|
| Drama 3 | 35B-A3B (3B active per token) | HuggingFace | New-generation flagship for multi-character scenes and long content, with multi-turn revision and local editing |
| S2-Pro | 4B parameters | HuggingFace | Previous-generation flagship with faster inference |
The model type is detected from the checkpoint's config.json, and both share the same command line and API server.
Fish Audio Drama 3
The new-generation voice model, upgraded across the board over S2-Pro.
Like the S2 series, Drama 3 supports multi-speaker generation, voice cloning and natural-language control, but it makes clear advances in long-form audio, interaction and editability.
Key features
- Multi-turn director revision: guide the previous take directly ("gentler, and a bit sadder"), and the model regenerates it with that context instead of starting over.
- Infilling and precise editing: edit audio the way you edit text — replace a single word ("Wednesday" → "Thursday") while the surrounding timbre and transitions stay natural.
- Scene-style multi-character production: voice a complete scene with several characters straight from a script description, with streaming support for long text.
- Long dialogues and long speech: built for long recordings and extended sessions, keeping characters and timbre stable throughout.
- Stronger expressiveness: laughter, crying, whispers and dramatic emotion are no longer flattened by the reference, so the delivery is much closer to a real performance.
- Multilingual voice cloning: sets a new level of SOTA for cross-lingual cloning error rates (CER / WER).
- Natural-language tag control: inline tags such as
[whisper],[angry]and[laughing]control emotion and prosody.
What changed compared with S2-Pro
| Capability | S2-Pro | Drama 3 |
|---|---|---|
| Multi-speaker | Supported | Supported, as scene-style multi-character production |
| Voice cloning | Supported | Supported, with lower multilingual error rates |
| Inline natural-language instructions | Supported | Supported |
| Local editing / infilling | Not supported | Supported |
| Multi-turn director revision | Not supported | Supported |
| Long content | Chunked generation | Long dialogues and long speech, with streaming |
| Strong emotion (laughter, crying, whispers) | Moderate | Stronger |
Results
Drama 3 takes a clear leap over S2 on public benchmarks: multilingual voice cloning (MiniMax Multilingual Testset), free-form speech editing (Ming-Freeform) and multi-turn emotion revision (Step-Audio-Edit), where control precision, multilingual error rates (CER / WER) and style accuracy all surpass the previous generation.
Read the technical report for the architecture, the training recipe and the full evaluation results.
Fish Audio S2-Pro
Our previous-generation flagship: natural-language controllable and emotionally expressive speech, about a hundred languages, and small enough to deploy on a consumer GPU.
- Inline natural-language instructions: tags such as
[pause],[excited]and[whisper]control prosody and emotion anywhere in the text. - Native multi-speaker generation: speaker IDs separate the characters inside one text, so you no longer generate and concatenate one speaker at a time.
- Rapid voice cloning: 10–30 seconds of reference audio is enough to reproduce a timbre.
- Single pass: long audio can be streamed out in one go.
- Production streaming: RTF 0.195 on a single H200, about 100 ms to first audio.
Visit the Fish Audio website for a live playground, and read the blog post and technical report for more details.
S2-Pro benchmark results (click to expand)
| Benchmark | Fish Audio S2 | |------|------| | Seed-TTS Eval — WER (Chinese) | **0.54%** (best overall) | | Seed-TTS Eval — WER (English) | **0.99%** (best overall) | | Audio Turing Test (with instruction) | **0.515** posterior mean | | EmergentTTS-Eval — Win Rate | **81.88%** (highest overall) | | Fish Instruction Benchmark — TAR | **93.3%** | | Fish Instruction Benchmark — Quality | **4.51 / 5.0** | | Multilingual (MiniMax Testset) — Best WER | **11 of 24** languages | | Multilingual (MiniMax Testset) — Best SIM | **17 of 24** languages | On Seed-TTS Eval, S2 achieves the lowest WER among all evaluated models including closed-source systems: Qwen3-TTS (0.77/1.24), MiniMax Speech-02 (0.99/1.90), Seed-TTS (1.12/2.25). On the Audio Turing Test, 0.515 surpasses Seed-TTS (0.417) by 24% and MiniMax-Speech (0.387) by 33%. On EmergentTTS-Eval, S2 achieves particularly strong results in paralinguistics (91.61% win rate), questions (84.41%), and syntactic complexity (83.39%).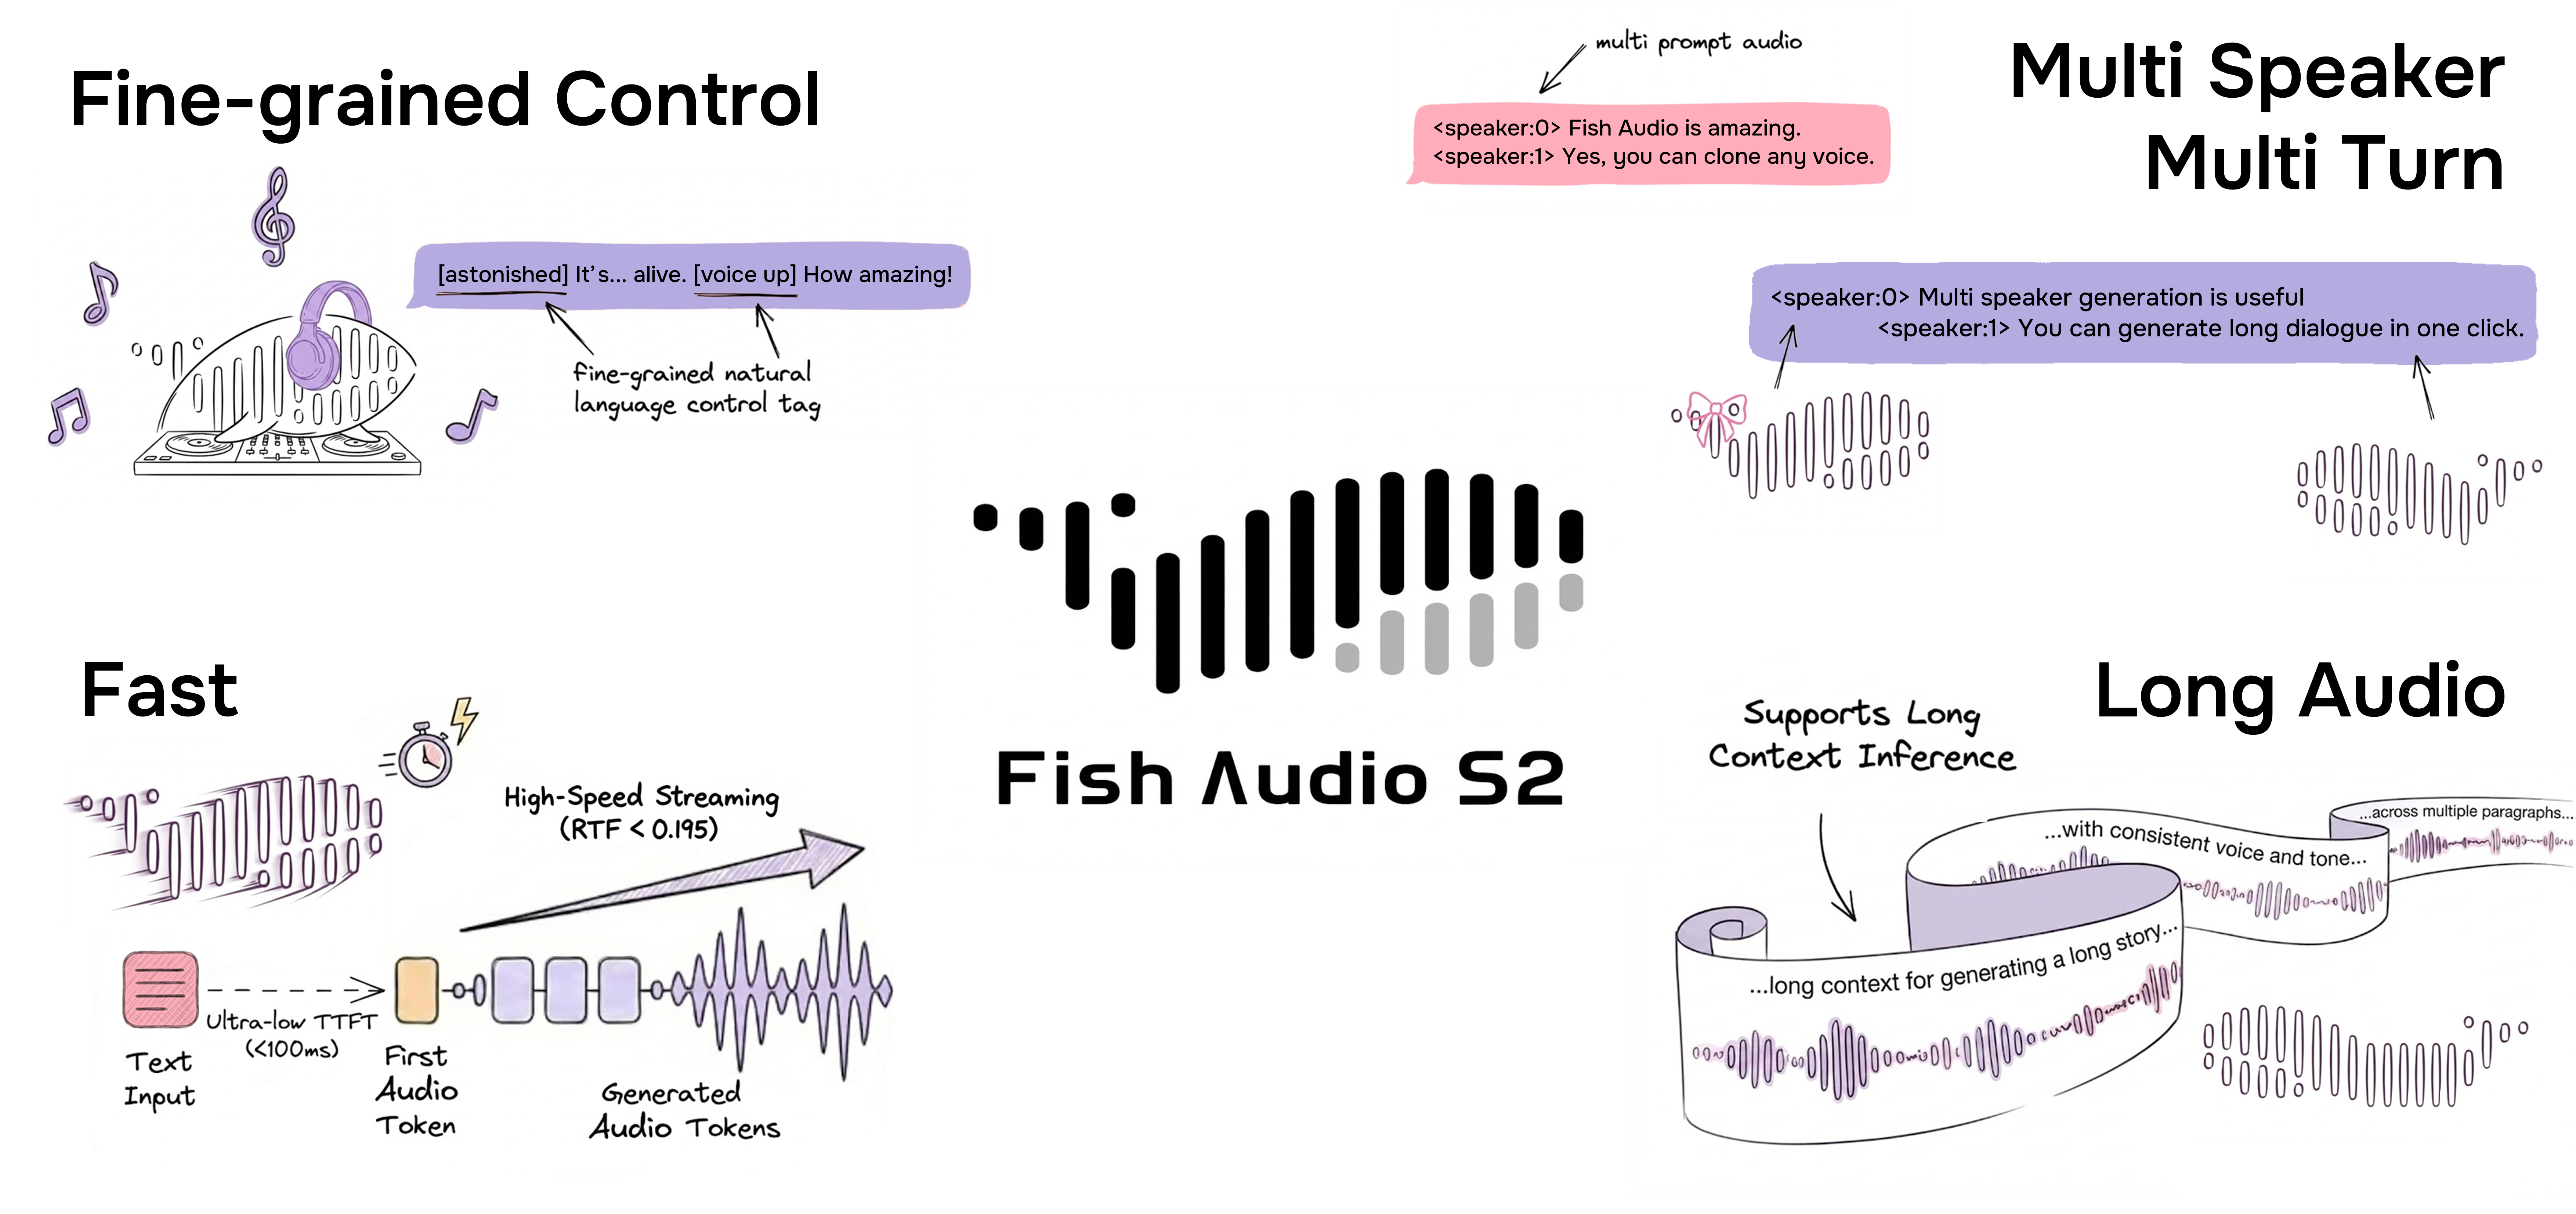
Credits
Tech Report
@misc{fish-speech-v1.4,
      title={Fish-Speech: Leveraging Large Language Models for Advanced Multilingual Text-to-Speech Synthesis},
      author={Shijia Liao and Yuxuan Wang and Tianyu Li and Yifan Cheng and Ruoyi Zhang and Rongzhi Zhou and Yijin Xing},
      year={2024},
      eprint={2411.01156},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2411.01156},
}

@misc{liao2026fishaudios2technical,
      title={Fish Audio S2 Technical Report},
      author={Shijia Liao and Yuxuan Wang and Songting Liu and Yifan Cheng and Ruoyi Zhang and Tianyu Li and Shidong Li and Yisheng Zheng and Xingwei Liu and Qingzheng Wang and Zhizhuo Zhou and Jiahua Liu and Xin Chen and Dawei Han},
      year={2026},
      eprint={2603.08823},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2603.08823},
}

@misc{fishaudio2026drama3,
      title={Fish Audio Drama 3 Technical Report},
      author={Fish Audio Team},
      year={2026},
      howpublished={Technical report},
      url={https://github.com/fishaudio/fish-speech/blob/main/docs/assets/Fish_Audio_Drama_3_Technical_Report.pdf},
}